Every startup wants to move fast. Ship the feature, close the round, hit the growth number. Data pipelines get built in a weekend, dashboards get duct-taped together, and nobody stops to ask whether the underlying data architecture can actually support what’s coming next. It works until it doesn’t.
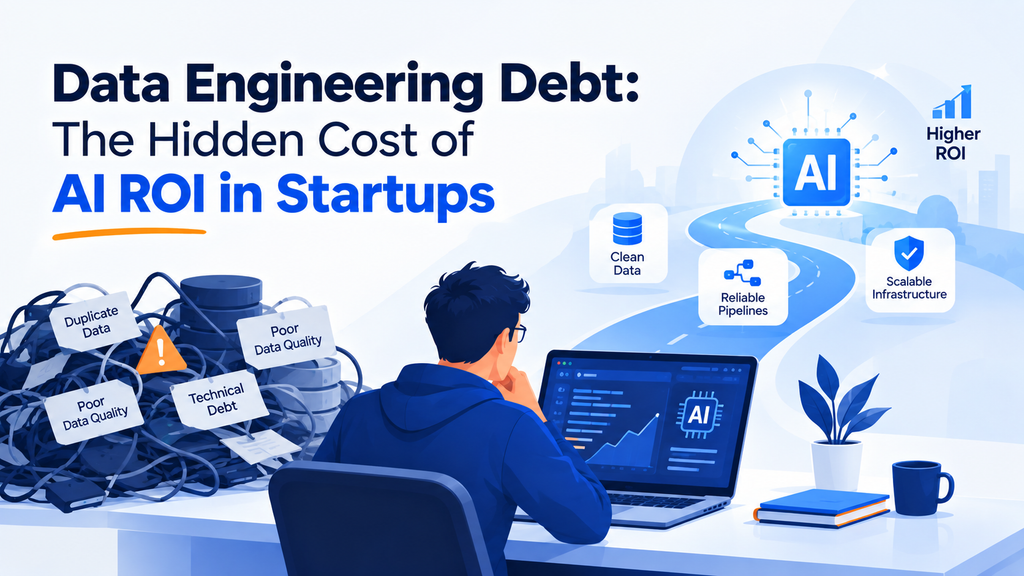
That’s the trap. Data engineering debt doesn’t announce itself with a crash or an outage. It shows up gradually, as models that underperform, dashboards that quietly disagree with each other, and data scientists who spend most of their week untangling messy inputs instead of building anything new. By the time leadership notices, the AI initiative that was supposed to be a competitive advantage has become a cost center with nothing to show for it.
This post breaks down what data engineering debt actually is, why it’s especially dangerous for startups betting big on AI, and what founders and technical leaders can do to pay it down before it sinks their return on investment.
What Is Data Engineering Debt, Exactly?
Data engineering debt refers to the compounding cost of shortcuts taken in how data is collected, stored, transformed, and maintained. It’s the data equivalent of technical debt: decisions that made sense under time pressure but create friction and risk down the line.
Think of it this way. When a startup launches, the engineering team is small, the data volume is manageable, and a quick-and-dirty pipeline that pulls data from a few sources into a spreadsheet or a basic database works just fine. But as the company grows, more data sources appear, more teams start relying on that data, and suddenly the pipeline that “worked fine” is the fragile backbone of decisions worth millions of dollars.
Common examples of data engineering debt include:
- Inconsistent schemas across systems that force engineers to reconcile data manually before it’s usable.
- Undocumented pipelines that only one person on the team fully understands a single point of failure waiting to happen.
- Duplicate or conflicting sources of truth, where the same metric produces different numbers depending on where you look.
- Manual data cleaning steps that were supposed to be “temporary” but became permanent parts of the workflow.
- No data validation or monitoring, so broken pipelines fail silently instead of triggering alerts.
- Hardcoded logic scattered across scripts and notebooks instead of centralized, reusable transformation layers.
- Untracked data lineage, making it impossible to trace where a data point came from or how it was transformed.
None of these issues are dramatic on their own. Together, they create a data foundation that can’t reliably support the machine learning models a startup is trying to build or the business decisions being made from dashboards.
How Does Data Engineering Debt Sabotage AI ROI?
AI models are only as good as the data feeding them. When that data is inconsistent, incomplete, or untrustworthy, every downstream investment in AI becomes shakier. This isn’t a theoretical risk it’s the most common reason AI projects fail to deliver the returns that were promised during the planning phase.
Here’s how the damage tends to unfold:
Model performance suffers first. Garbage in, garbage out still holds true no matter how sophisticated the model architecture is. A well-tuned model trained on messy, mislabeled, or inconsistent data will underperform a simpler model trained on clean data. Worse, the model might appear to perform well in testing, only to produce unreliable outputs in production where the data is even messier.
Engineering time gets redirected. Data scientists and machine learning engineers who are often the most expensive hires on a startup’s payroll end up spending the majority of their time on data cleaning and pipeline firefighting instead of model development. Studies consistently show that data scientists spend upward of 60 to 80 percent of their time on data preparation rather than modeling. That’s a direct hit to ROI: you’re paying premium salaries for work that doesn’t move the AI roadmap forward.
Trust erodes across the organization. Once stakeholders catch a model or dashboard producing conflicting numbers, they stop trusting the output. Adoption drops, even if the underlying model is technically sound. An AI system nobody trusts delivers zero ROI, regardless of its accuracy. This trust deficit is extremely hard to recover from once a team learns to ignore the AI tool, getting them back takes far more than fixing the underlying data.
Scaling becomes exponentially harder. A messy pipeline that barely works for one use case becomes unmanageable when a startup tries to add a second or third AI product. Each new initiative inherits the same broken foundation, and every patch applied to fix one problem tends to introduce new ones. Debt compounds, just like financial debt, and the interest rate only goes up over time.
Regulatory and compliance risk increases. As startups grow, they often become subject to data regulations GDPR, CCPA, HIPAA, and others. A data environment with poor lineage tracking, undocumented transformations, and inconsistent storage practices creates real legal exposure, not just operational headaches.
Why Do Startups Accumulate Data Engineering Debt So Fast?
Startups are especially vulnerable to this problem for a few structural reasons that are worth naming directly, because understanding the cause is the first step toward fixing it.
Speed Is Rewarded Over Structure
Early-stage teams are optimized for shipping fast and proving product-market fit. That’s appropriate a startup that moves too slowly dies. But investing in clean data architecture doesn’t show up on a pitch deck, so it’s easy to deprioritize in favor of features that customers can see and investors can measure. The people making the build-vs.-invest decision often don’t feel the downstream cost of bad data until it’s already severe.
Small Teams Wear Too Many Hats
A startup’s first data hire is often responsible for everything from building pipelines to running analytics to supporting the AI roadmap. There’s rarely bandwidth to step back and build sustainable infrastructure when there are three fires to put out today. The result is a collection of one-off solutions built under pressure, none of which were designed to work together long-term.
AI Ambitions Outpace Data Maturity
Many startups want to bolt AI features onto their product before they’ve established reliable data collection and governance practices. This is understandable AI is exciting, and the pressure to ship AI-powered features is real. But the excitement around AI capabilities often outruns the unglamorous but necessary work of getting the data foundation right. You can’t build a reliable recommendation engine on top of user data that hasn’t been cleaned or deduplicated.
There’s No Clear Owner
Without a dedicated data engineering function, responsibility for data quality gets scattered across product, engineering, and analytics teams. When everyone is a little bit responsible, no one is fully accountable, and debt accumulates in the gaps. This diffusion of ownership also means there’s rarely a single person advocating for data infrastructure investment in budget conversations.
Tooling Choices Made Early Can Lock You In
Early choices about databases, pipeline tools, and data formats tend to persist far longer than intended. What works for a thousand users often breaks at a hundred thousand, but migrating to a new stack while maintaining business continuity is painful and expensive. Startups that choose the wrong tools early or that don’t document their architecture well enough to migrate later often find themselves trapped.
What Are the Warning Signs of Data Engineering Debt in a Startup?
Data engineering debt is often invisible until it isn’t. The signs tend to emerge gradually, which is part of what makes the problem so easy to underestimate. A few signals suggest it’s already becoming a problem:
- Team members routinely ask, “Which number is correct?” when looking at reports.
- Data scientists spend more time in spreadsheets and cleaning scripts than in modeling notebooks.
- New data sources take weeks to integrate instead of days.
- AI features are delayed repeatedly due to “data issues” rather than model performance.
- Onboarding a new engineer to the data stack takes far longer than it should, because nothing is documented.
- A pipeline breaks and it takes hours or days just to figure out where the failure occurred.
- The same dataset exists in multiple places with different values, and nobody is sure which one is authoritative.
If more than one of these sounds familiar, it’s worth pausing to assess how much debt has built up before committing further AI investment. The tendency is to push through and hope things improve organically they rarely do.
How Can Startups Pay Down Data Engineering Debt Without Stalling Growth?
The good news: data engineering debt is manageable, and it doesn’t require pausing the business to fix. It requires a deliberate, prioritized approach that balances short-term delivery with longer-term infrastructure health.
Audit before you build. Before launching a new AI initiative, map out where the data actually lives, how clean it is, and where the inconsistencies are. This step alone often reveals which “AI problems” are really data problems in disguise. A two-week audit can save months of rework later.
Establish a single source of truth. Pick one system of record for each key metric or entity, and route everything else through it. This eliminates the conflicting-numbers problem that erodes trust across the organization. It also forces important conversations about which definitions are canonical which is itself a valuable exercise.
Invest in data validation early. Automated checks that catch broken pipelines or unexpected data shifts save far more time than they cost to build. Tools like Great Expectations, dbt tests, or even lightweight custom scripts can alert teams to problems before they propagate downstream. Prioritize validation for AI-critical data pipelines first if resources are limited; less critical systems can wait.
Document as you go. A lightweight data dictionary or pipeline map prevents knowledge from living in one engineer’s head. Even a simple README that explains what each table contains and how it’s populated is vastly better than nothing. This becomes essential the moment that engineer goes on vacation, moves to another team, or leaves the company.
Modularize your pipelines. Spaghetti pipelines where everything connects to everything else in undocumented ways are one of the most common sources of debt. Breaking pipelines into discrete, well-defined stages makes them easier to test, debug, and update without unintended side effects.
Set data quality SLAs. Treat data freshness, completeness, and accuracy as requirements, not afterthoughts. If the business depends on daily model predictions, then the pipeline that feeds those predictions needs an uptime and latency target just like any customer-facing service.
Treat data engineering as a product, not a chore. Assign clear ownership, set quality standards, and revisit the data roadmap with the same rigor applied to the customer-facing product roadmap. Data infrastructure has users too they’re just internal.
What Does Good Data Engineering Look Like at an Early-Stage Startup?
Good data engineering doesn’t mean building enterprise-grade infrastructure on day one. It means matching the level of investment to the stage of the company while avoiding shortcuts that create outsized future costs.
At the seed stage, a simple, well-documented pipeline that reliably moves clean data from source to destination is worth more than a sophisticated but unmaintainable setup. The goal is repeatability and trust, not sophistication.
At the Series A and beyond, as AI becomes central to the product and the data team grows, the bar rises. This is the stage where investing in a proper data warehouse, orchestration tooling, automated testing, and data governance starts to pay clear dividends. Teams that built clean foundations early will scale much faster than those who have to rebuild under pressure.
Choose lightweight, well-documented pipelines if the team is small and the data volume is modest. Choose more robust, automated infrastructure once AI becomes central to the product and the cost of bad data starts outweighing the cost of building it right. The key is recognizing that transition point before debt forces the decision ideally before a failed AI launch makes the cost of delay impossible to ignore.
The Hidden Competitive Advantage Nobody Talks About
Here’s something that doesn’t get discussed enough in startup circles: a clean data foundation is a competitive moat. Companies that invest in data quality early can ship AI features faster, with higher confidence, and with less rework. They can run experiments reliably. They can onboard new team members quickly. They can pivot without losing months of work untangling messy infrastructure.
Startups that treat data engineering debt as someone else’s problem to solve later end up in a position where every AI initiative is slower, more expensive, and less reliable than it should be. Meanwhile, the startup that took the time to build a clean foundation ships a new AI feature in two weeks that would take the debt-laden competitor six months.
This isn’t a minor operational detail. It’s a strategic differentiator that compounds over time, just like the debt it prevents.
Fix the Foundation Before You Scale the Ceiling
AI can absolutely deliver strong ROI for startups, but only when it’s built on a data foundation that can support it. Data engineering debt is easy to ignore because it doesn’t cause visible failures right away. It just quietly taxes every AI initiative, a little more each quarter, until the returns don’t justify the investment anymore.
The startups that get the most out of AI aren’t necessarily the ones with the most advanced models or the biggest GPU budgets. They’re the ones that treated their data infrastructure as a strategic asset from the start and kept paying attention to it as the company grew. If AI is central to your roadmap, the smartest next step isn’t a new model or a bigger compute cluster. It’s an honest audit of the data feeding everything you’ve already built.
Start there. Fix what’s broken. Document what you know. Then build.